Problem/Justification
Below @Stux has done a great video on how to setup tiered snapshots which is great:
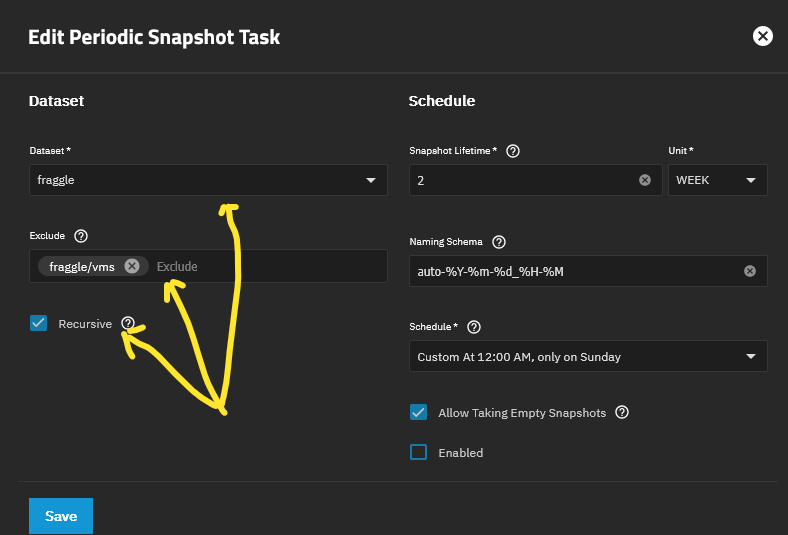
This relies on adding the whole pool and then excluding datasets you do not want for the various snapshot tasks.
Want I would like
I would like the ability to include datasets along with an optional Recursive option for each one which would allow much better control of periodic dataset snapshots especially of you have a Pool with dynamic datasets (i.e. datasets created and deleted often or just programatically)
I could then set my snapshot tasks up and not have to worry or be concerned when I add or remove a dataset.
So this would manifest as an Include selector and for each entry there would be an option to select Recursive. for that dataset. TrueNAS would build the “complex” command in the background and that is why this would be possible as I appreciate this is probably a lot more difficult that the current mechanisms.
Impact
It would allow a more advanced control of tiered snapshots
User Story
n/a
Just out of curiosity, what is the use case for creating/deleting datasets on a regular basis?
Also, if you have been able to create/delete datasets programmatically, you would be able to create snapshot schedules programmatically as well (welp, I just assume that midctl has a method for this).
This was more of a scenario to aid with my question. But to try another angle of explain my thoughts consider this:
I have my apps setup and they are getting backup as expected on an hourly and daily basis using Stux tiered backups (whole pool with exceptions) I then add on a new folder called bittorrent but I don’t want that in my backups so to add the the bittorrent dataset I have to:
- disable all
periodic snapshot tasks
- create the
bittorrent dataset
- add an exception into all
periodic snapshot tasks
- restart all
periodic snapshot tasks
This leads to a small window where snapshots are not being run. If I just added the bittorrent dataset this could potentially pollute my backups. It is true to say it is not the end of the world but I want to try and get things neat and tidy because I have a suitable protocol in place.
Going back to the OP, having an include with recursive option allows me to me setup tiered snapshots without the issue I have outlined.
You have at least 2 solutions for this:
- Have different top-level datasets, some of which are excluded from different tiers. Then create the new dataset under some of those top-level depending on desired tiers.
- You can just remove the new dataset from the longest tier schedules after creation. No need to remove it from shortest tiers (like minutely, hourly) because they consume very little space. And it’s unlikely that the longest tiers would create snapshot right after the dataset is created (because they make snapshots very rarely – once a day, once a week, or once a month).
I’ve already suggested these solutions to you in another thread.
This is different to the solutions you have given me. This is a different one that requires a features request. 
No, they are the same. I just described them a bit differently to not repeat myself and for the message to be self-sufficient.
Of course they are different. I’m just saying that your use case is already solvable.