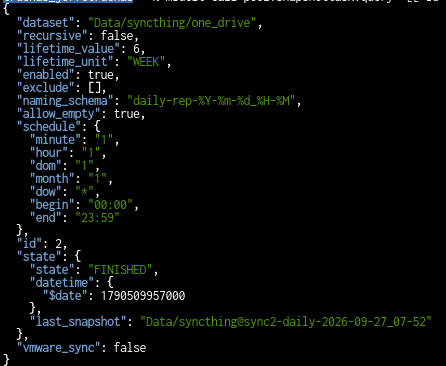
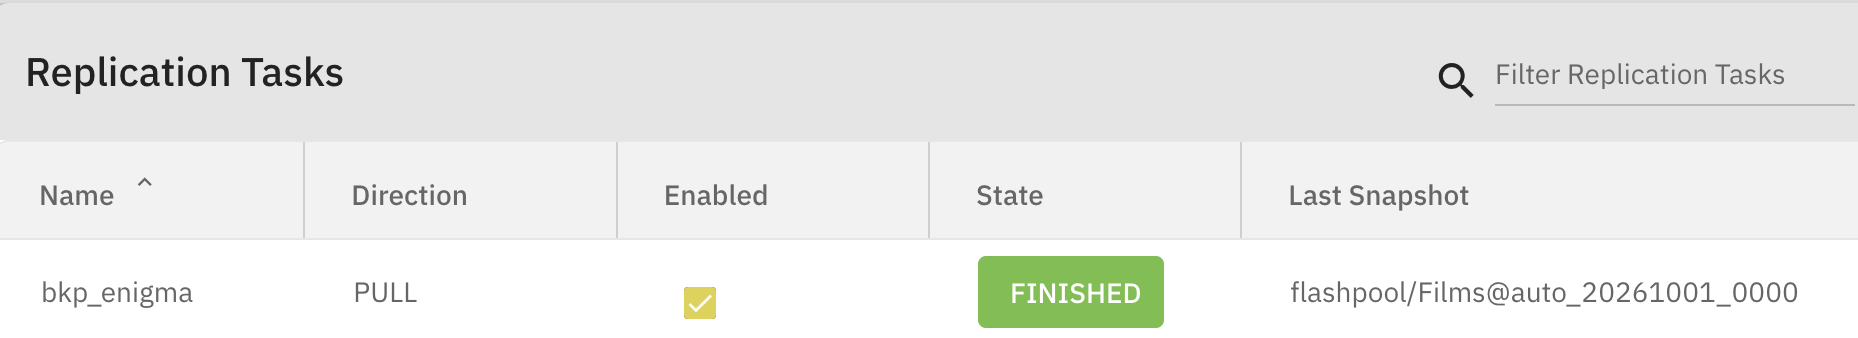
I’ve had some tiered snapshots running for a while and am now trying to add several different time frame replication tasks. Wanting to separate these snapshots from the prior testing ones I changed their naming schemas. I get one of the replications to run, the rest complain “failed: No incremental base on dataset ‘Data/….’ and replication from scratch is not allowed..”
This semi-testing dataset has many snapshots now, with a variety of different names, most of which are empty. Is there a need to maybe cleanup this mess? How does one create the missing incremental base, I wrongly assumed manually creating a snapshot using each new schema called for by the replications task would do it, no joy.
naming schema mismatch will do that. the replication task only treats snapshots that match its own naming schema as a base.
id try:
-zfs list -t snapshot -o name,creation Data/YOURDS
-make the periodic snapshot task naming schema the same string the replication task expects
-or tick replicate from scratch once so it seeds a full copy, then untick it
-manual snaps only count if the name matches that schema pattern
empty test snaps can go. they wont invent a base for u tho.
I tried the replication from scratch, which certainly works, but it removes any current replicated snapshots. Is it not possible to have several replication tasks with different naming for the same dataset? I’m trying to create daily, weekly and monthly replications, for differing retention.
That’s great to know, being new to this more research is needed then. Is there a reference you’d suggest I look at possibly. It seems odd to need more than one Rep task, as the daily snapshots provide all that’s needed, only some would be re-badged. The task would need to apply comparison, lifetime and replication renaming for more than a single schema.
Maybe a script is required for this, but I’d certainly prefer the UI. I’m already setup to run daily or longer interval snapshots and replication tasks from a script, as the nas is off much more than it’s on.
I achieve what you want with three snapshot tasks (daily, weekly, monthly) with the same namining convention but different schedules and retention times; then my backup server runs a single daily PULL replication task (since there’s only one naming scheme).
It works as intended… as long as I do not touch it. Amending the scheme now could break replication or lead to unwanted pruning of snapshots (though using pull replication rather than push somewhat protects the backup).
Be cautious… or just use one replication task by naming scheme.
That’s interesting! Am I correct that the replicated snapshots will keep the different lifetime settings, so long as the replication task is set to match the snapshot lifetime? Brilliant!
The script decides when to run the snapshot tasks based its last completed time stamp and desired interval, then can run the replication task. I’m a bit unclear on whether or not completion of a snapshot automatically runs a replication task using the same scheme.
the monthly of September 1st and weeklies of 7th and 14th have survived the pruning of dailies even though there is no difference in naming convention [not to mention a switch from TrueNAS CORE to FreeCORE during the period…]
I generally turn off at least the backup when I go on holidays. Because it is pull replication no error is logged, irrespective whether the main remains on, and it catches up silently when turned on again after I return.
That’s encouraging. The replicated snapshots show no destruction date, and some forum threads suggest it shouldn’t work (so far as replicated pruning), but it apparently does. It’ll be a couple weeks before I can validate the pruning.
I’ll have the script that calls these tasks loop through the snapshots starting with the longest time gap, continuing with the first one to hit.
Update:In the end this scheme didn’t work, since the shapshot names didn’t happen when scheduled by the snapshot tasks, due to being script initiated.
What has worked was to have the post-init script also change the snapshot names to align with one of the three snapshot tasks (daily, weekly, monthly) expected day/time stamps. Retention then takes ownership, displays destruction dates and prunes both pools.
fwiw, changes to or different/multiple naming schemes are no problem as long as you are cleaning up behind yourself at a later time on the target if for instance you want to change it to something more descriptive but only want to keep a certain amount/age of snapshots on the replica. The old stuff will be left alone in terms of the “snapshot retention policy” iirc.
Cool, thks for the note. Ive seen threads where some suggest it’s not good practice to use middleware commands, that they may be depreciated in the future. It works great for now.
only using, for example
midclt call pool.snapshottask.query
midclt -t “$REPL_TIMEOUT” call -j replication.run “$rid”