Just got this alert, which may be related, though I don’t really know what it means:
SMB shares have path-related configuration issues that may impact service stability: MainStorage: ACL type mismatch with child mountpoint at /mnt/MainStorage/scripts: MainStorage - POSIX, MainStorage/scripts - NFSV4
The message mentions an ACL mismatch, which suggests maybe it is if you’re blaming ACLs? But again, I don’t know what that is, other than an anterior cruciate ligament.
Are you SMB sharing the whole MainStorage pool?
That’s not recommended and I thought it wasn’t possible anymore. Perhaps this is a grandfathered setup.
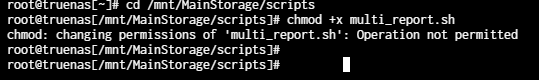
It looks like you indeed have ACLs applied, likely your Datasets → Click the MainStorage-dataset → Edit → Advanced Options → ACL Mode is set to Restricted. That prevents chmod from working, as a precaution.
Workarounds is changing the ACL Mode from Restricted to Passthrough, or not using ACLs for that dataset at all. I suppose you could also change the ACL Type to POSIX for MainStorage/scripts, unless you specifically need NFSV4 ACLs for that dataset.
Okay, I got it to run. Got an email with CRITICAL ERROR in the subject line. I think it’s just that the pool is degraded, but it just contains a massive dump of info rather than explaining up front what the critical error is.
Read the CRITICAL LOG FILE, this explains what triggered the Critical. Also, read the User Guide, it should be where your script is located. It isn’t a fully featured user guide, there is some stuff you should know already about what data you are reading. Visit the Wiki page on S.M.A.R.T. and it explains a lot. It is technical, sort of.
RUNNING SHORT TEST: sda sdd sde sdf sdg sdh nvme0, ‘sdb sdc’ moved from LONG TEST due to SCRUB.
Drive sda is still running a test: (10% remaining)
Drive sdd is still running a test: (10% remaining)
Drive sde is still running a test: (10% remaining)
SMART command for drive:sdf was not good, returned exit code:1
Lets try a different interface type…
SMART command -d auto for drive:sdf was not good, returned exit code:1
Lets try a different interface type…
SMART command -d sat for drive:sdf was not good, returned exit code:2
Lets try a different interface type…
SMART command -d atacam for drive:sdf was not good, returned exit code:1
Lets try a different interface type…
SMART command -d nvme for drive:sdf was not good, returned exit code:2
Lets try a different interface type…
SMART commands exhausted for drive:sdf, returned exit code:2
That is not true, I see three drives in test. Looks like you are running the script several times quickly. What exactly is drive sdf? (Exact Model) and how is it physically connected to the system?
If you are able to get smartctl to run a test on that drive, please let me know the parameter you used. The parameter I’m talking about is the smartctl -d ???? -t short /dev/sdf where ??? is the interface mode. You will need to look at the smartctl manual (google smartctl man debian) to see the options. It is a hit and miss game. If you find one that works, let me know and we can add it to the script.
For the other tests, if a test is in progress, another test cannot commence. Three of your drives were in test with 10% remaining.
With that said, if you have drives which take longer than 24 hours to complete a SMART Long test, you will see this issue whenever you run a Long test, 24 hours later. The report from email will tell you it is in test.
For all users that have updated the sendemail to the 1.60 before an half hour ago using the multi report built in updater: you should update again the sendemail to avoid the script not working on the next launch. Unlucky i have made a mistake on committing the right latest file for the one used by multi report.
Not probably, but if the update has been performed via the sendemail command, everything will be ok and no actions will be necessary.
Sorry for the inconvenience
If it’s only testing two per day, how can that be? And why do my emails keep reporting “Drive(s) previously scheduled to be tested: None
Drives scheduled for testing today: None”?